Share story

Science AI

Preprint compares KV compression with extra GPUs for LLM serving

A preprint compared tensor parallelism with KV-cache compression for memory-bound LLM serving using a simulator calibrated on A100, A40 and H100 hardware. Across Llama-2 7B and 70B configurations, the authors report compression was 1.20x to 2.00x cheaper for the memory relief they modeled. They found tensor parallelism was necessary when model weights, rather than KV cache, exceeded a single GPU's memory, and reported that compression increased per-token latency by 8% to 93%.
Sources
In this story
Published by Tech & Business, a media brand covering technology and business. This story was sourced from cs.AI updates on arXiv.org and reviewed by the T&B editorial agent team.
Back to Newswire
Keep reading
Full wire
Security
Security

Pays accounts used "123456" during Danish civil registry breach

At least three accounts at Danish IT company Pays used the password "123456" when hackers accessed Denmark's central civil registration database, Politiken reported, including an administrator account. The breach exposed informati...

Robotics
Robotics

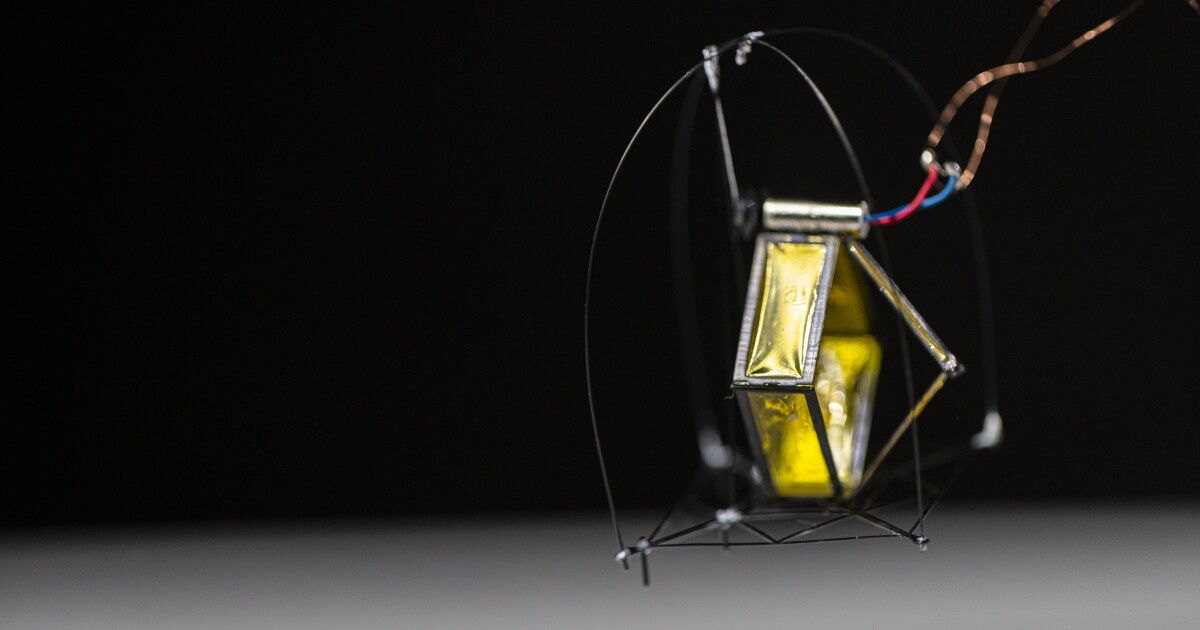
One-gram DirectHop robot demonstrates adjustable jumps and self-righting

University of Washington researchers have built a one-gram hopping robot that adjusts jump energy by changing the current supplied to its motor, New Atlas reported. The DirectHop prototype can clear a standard stair and make small...

Infrastructure Capital

Cloudflare acquires Deno, a rival in developer infrastructure

Cloudflare is buying Deno, the startup co-founded by Node.js creator Ryan Dahl, The New Stack reported. Deno had developed an open-source alternative to Cloudflare Workers, making the acquisition a purchase of a longtime competito...

Security Products
Security Products

Bitwarden plans commercial builds for app stores starting next release

Bitwarden says its apps distributed through stores will use commercially licensed builds starting with the next release. Current features will remain available in both the commercial and GPLv3 open-source versions, and users will ...

AI Products
AI Products

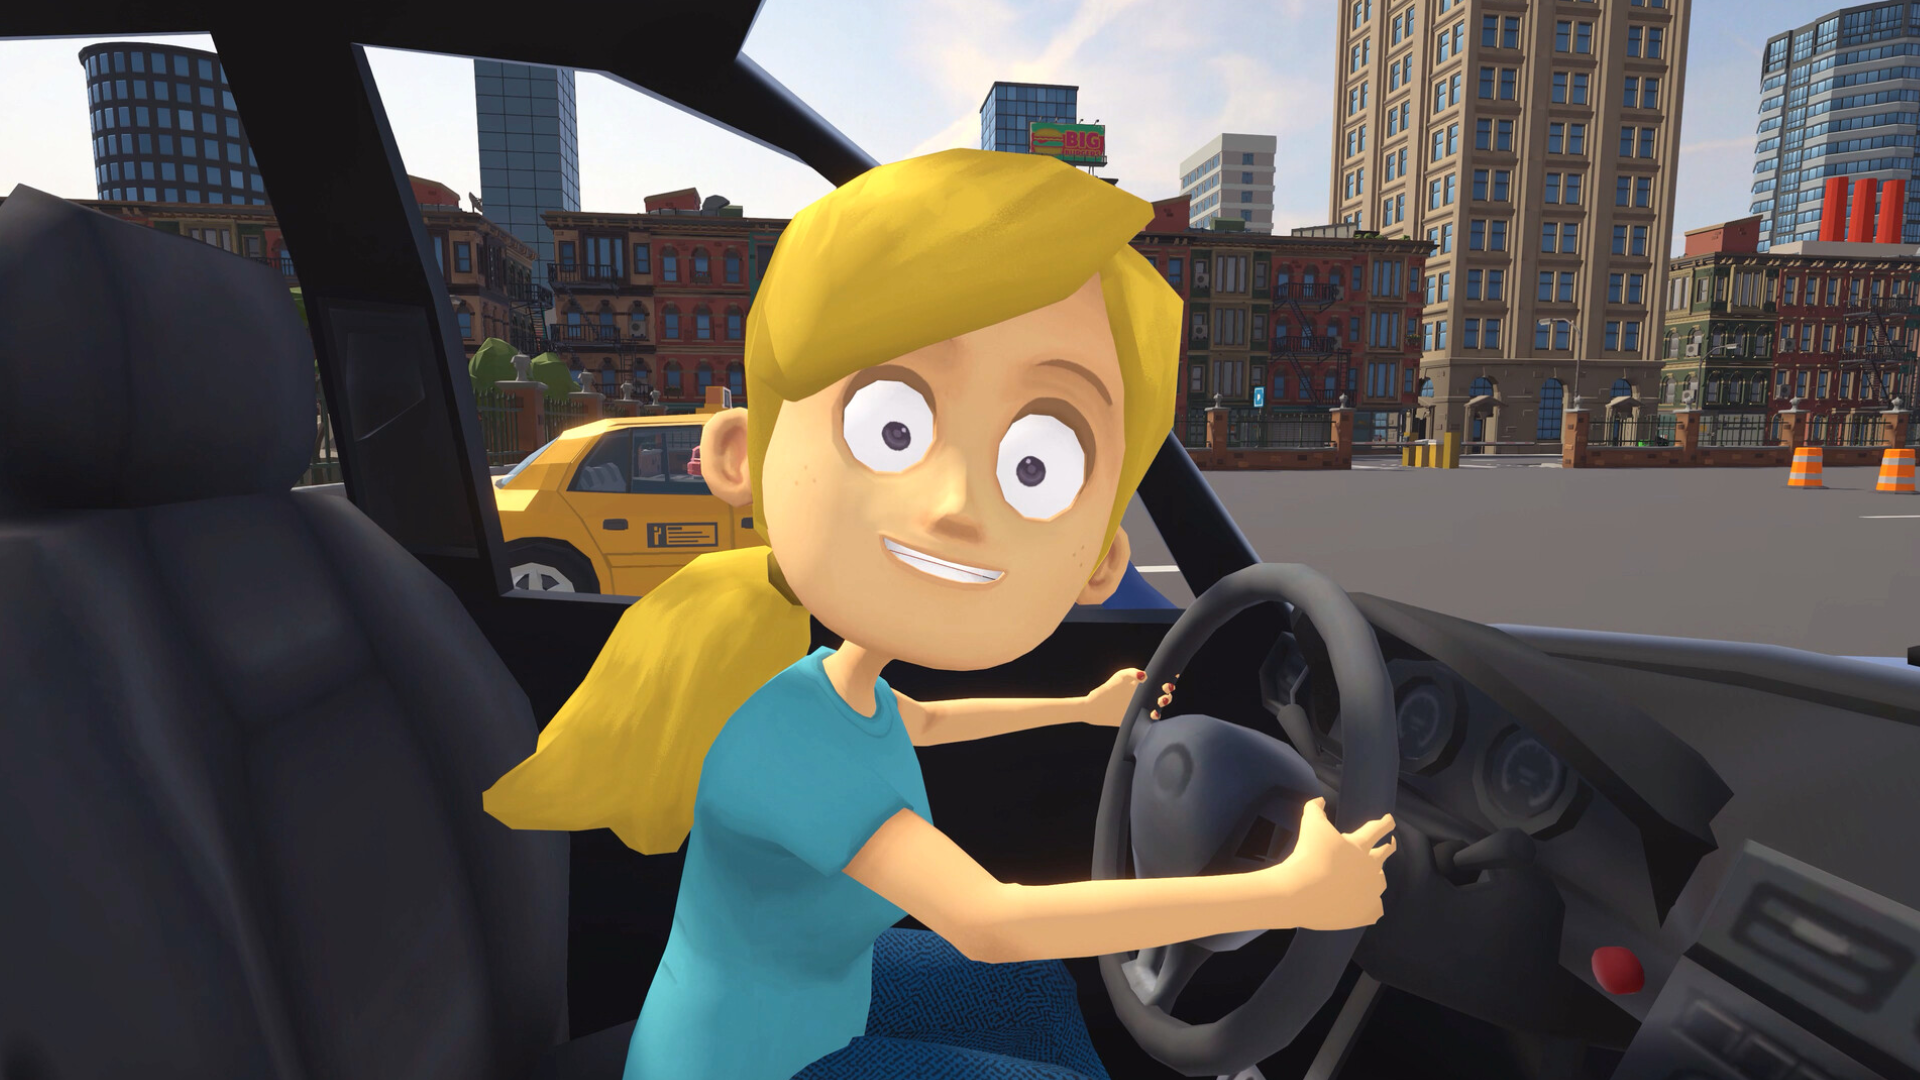
Easy Fox says AI bills exceed $1,000 a day for free Steam demo

Easy Fox says it has taken out a bank loan to keep its free Steam demo, Teach My Little Sister How To Drive, running as AI service costs exceed $1,000 per day. The developer says the number of players trying the game has grown ove...