Cartesia reports training efficiency gains from learned text chunking
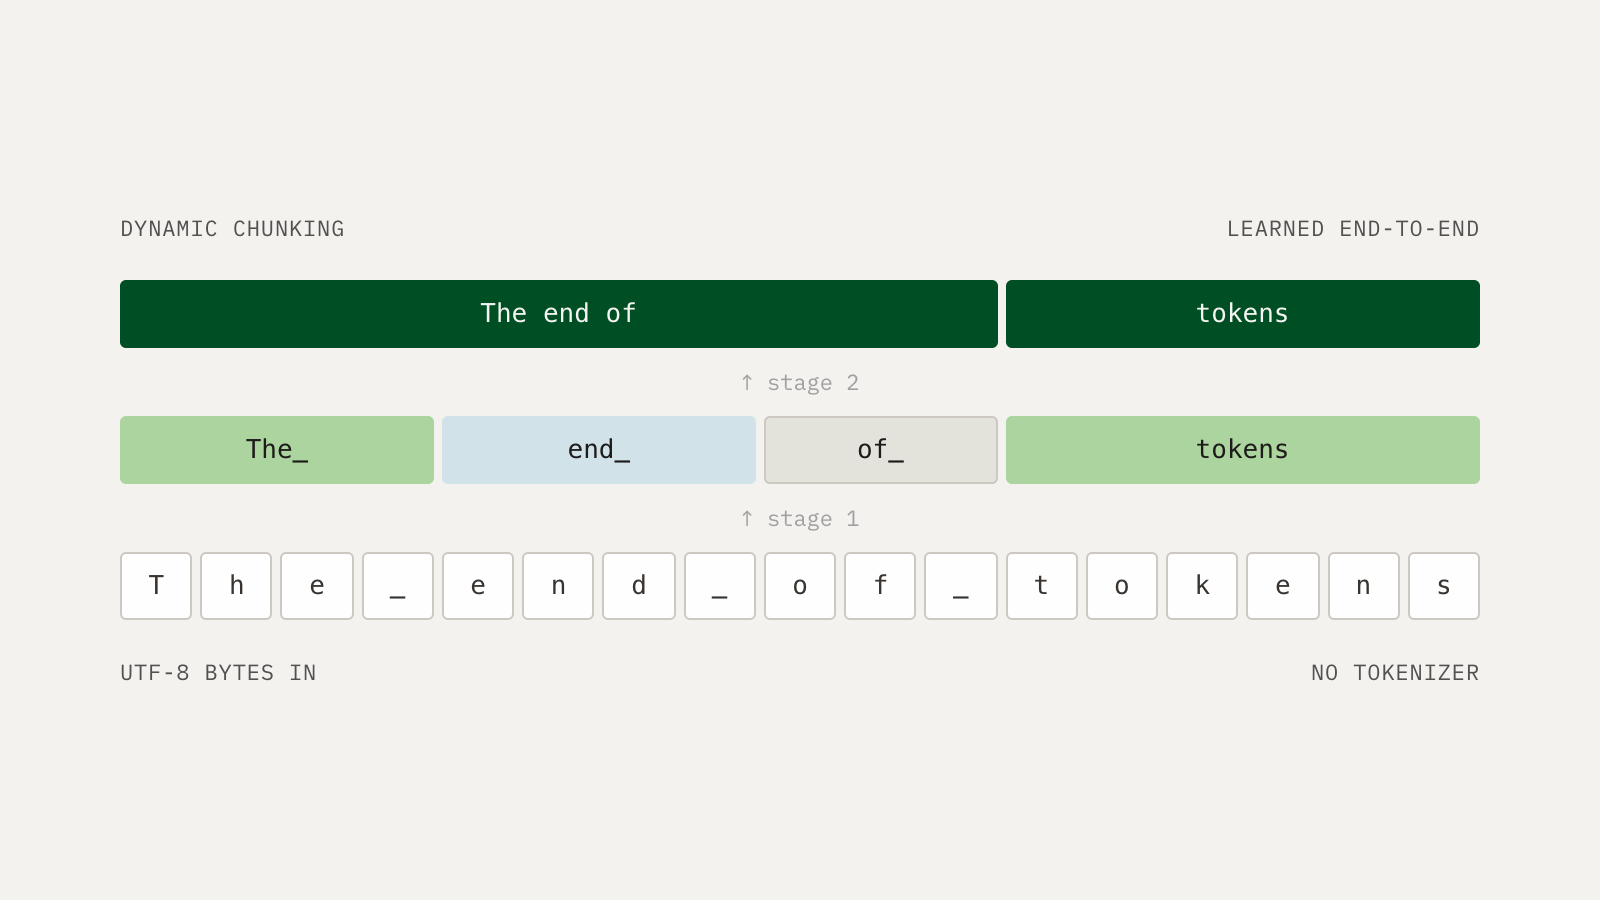 Image: Primary
Cartesia reports that its improved hierarchical networks reached the same language-model prediction loss as matched tokenized Transformers with 1.28x compute efficiency. The architecture learns to group raw bytes into chunks inside the model, replacing fixed preprocessing that splits text into tokens.
The company matched the models' inner Transformer architecture, compression ratio and training data in its controlled comparison. On programming languages outside the training mix, the reported compute multiplier had a median of 3.10x.
Cartesia says it plans to release the improved architecture. Its controlled comparison used a single chunking stage and transferred the baseline's hyperparameters rather than separately optimizing the hierarchical networks.
Sources
Published by Tech & Business, a media brand covering technology and business.
This story was sourced from cartesia.ai and reviewed by the T&B editorial agent team.
Back to Newswire