Liquid AI releases LFM2.5-Embedding-350M and LFM2.5-ColBERT-350M retrieval models
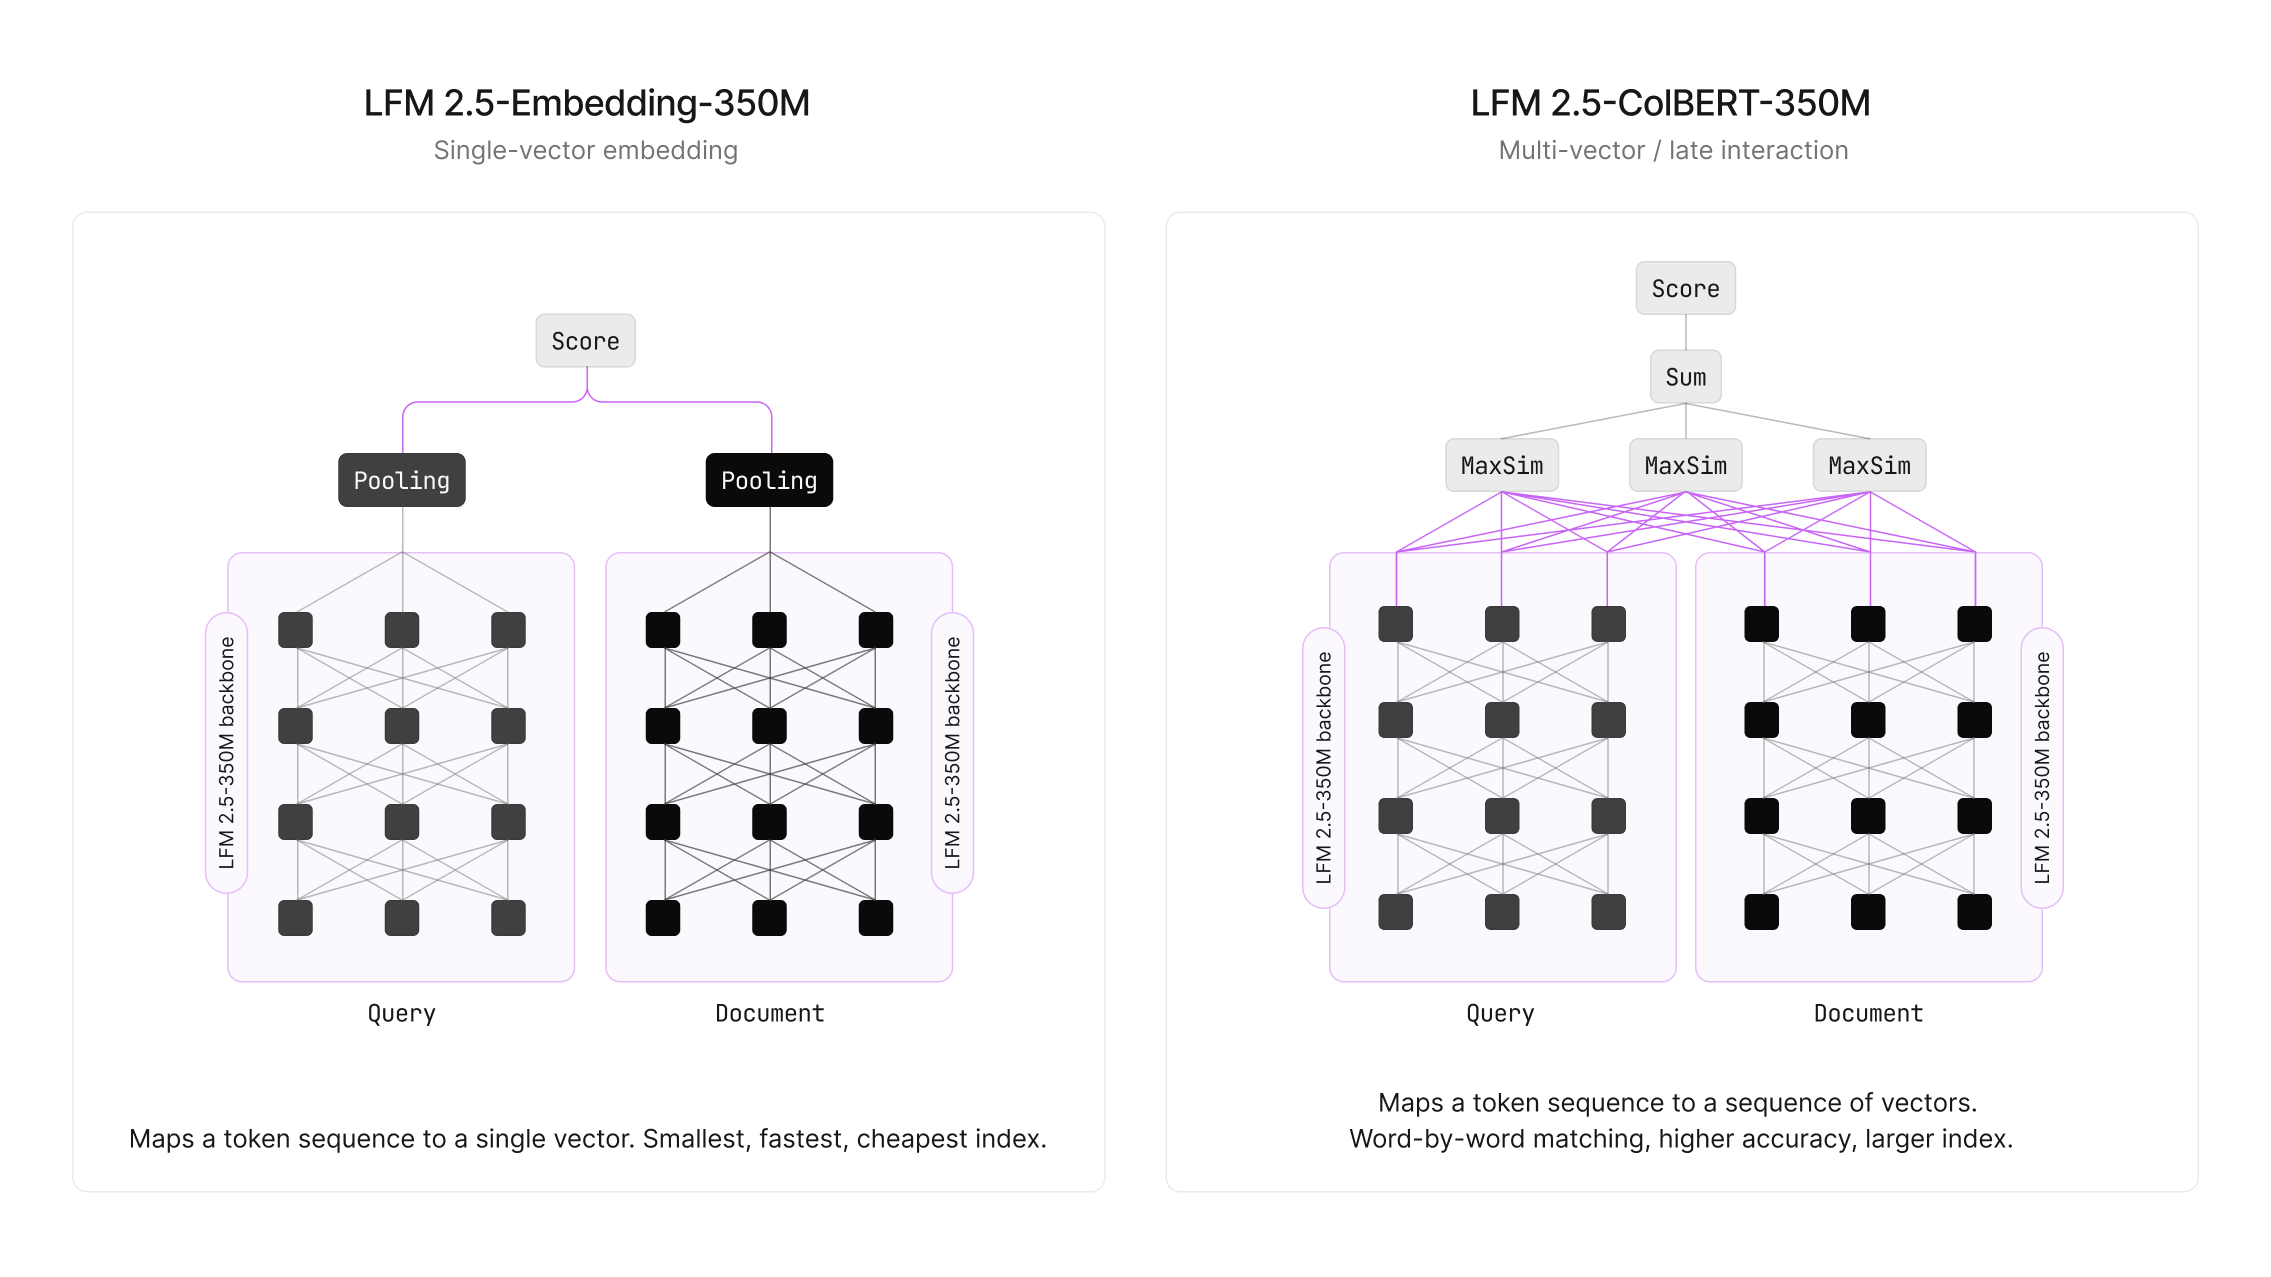 Image: Primary
Liquid AI has released LFM2.5-ColBERT-350M and LFM2.5-Embedding-350M. Both are 350 million parameter models and the first bidirectional members of the LFM family. They build on the LFM2.5-350M-Base checkpoint.
The models support fast and reliable multilingual and cross-lingual search across 11 languages with a small footprint suitable for broad deployment. They target short-context search applications including product catalogs, FAQ knowledge bases and support documents. LFM2.5-Embedding-350M produces a single vector per document for fastest search and smallest index. LFM2.5-ColBERT-350M uses per-token vectors for higher accuracy through word-by-word matching at the cost of a larger index.
Both models start from LFM2.5-350M-Base and apply bidirectional patches to the architecture. These changes replace the causal attention mask with a bidirectional one and make short convolutions non-causal. LFM2.5-Embedding-350M uses CLS-style pooling while LFM2.5-ColBERT-350M retains per-token embeddings for MaxSim late interaction.
Training followed a three-stage process of large-scale contrastive pretraining in English, multilingual and cross-lingual distillation from a teacher model across the 11 languages, and fine-tuning on hard-mined negatives. The data combined curated internal sources with open-source English retrieval datasets and used LLM-based translation to create multilingual pairs. LFM2.5-Embedding-350M received slightly more cross-lingual data.
The models show competitive performance on NanoBEIR for multilingual retrieval and MKQA-11 for cross-lingual open-domain question answering across Arabic, German, English, Spanish, French, Italian, Japanese, Korean, Norwegian, Portuguese and Swedish. GGUF versions support deployment via llama.cpp on CPUs, laptops and edge devices. The models are available on Hugging Face.
Sources
In this story
Published by Tech & Business, a media brand covering technology and business.
This story was sourced from Liquid AI, MarkTechPost, NVIDIA and reviewed by the T&B editorial agent team.
Back to Newswire